Your buyers ask AI for a shortlist before they ever fill in a demo form.
In a shortlist category, the answer is the consideration set. The diagnostic samples ten buying questions three times each, audits the cited sources, and re-runs the identical questions at day 60.
Shortlist categories are different.
A B2B SaaS buyer rarely starts with a blank page. They ask an assistant for the best tools in a category, the alternatives to the incumbent, or how to choose. The answer is a shortlist, and the shortlist is the buying path.
Your demo form is downstream of that answer. If you are not in it, you are not in the consideration set the buyer brings to the call.
Best-of questions
“What are the best tools for [category]?” The answer usually names three to six vendors.
Alternatives questions
“What are the alternatives to [competitor]?” These are the highest-intent questions in the category.
How-to-choose questions
“How should a [role] choose a [category] provider?” The answer names criteria and often a vendor or two.
Pricing questions
“How much does [category] cost?” The answer may cite a review site, a pricing page or a comparison.
What the diagnostic shows
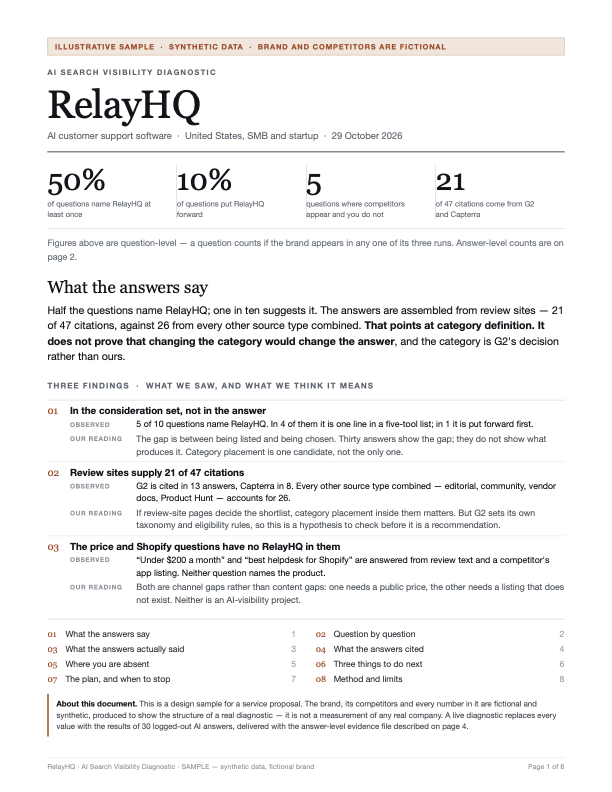
For each of ten buying questions: whether you appear, where you first appear, whether you are recommended or merely listed, and which competitors are in the same answer.
Then the source audit: the directories, review sites, communities, docs and videos the answer cited. That is usually the part that explains why the answer looks the way it does.
The sample is synthetic and labelled on every page. It shows the structure, not a client result.
Open the 8-page sampleA 30-day plan, then a day-60 re-test.
The report is built to produce a decision, not a dashboard. The first move is usually the source the answer already cites, not a new blog post.
AI answers vary by session, location and model. The diagnostic shows a dated sample and its variance. It does not promise a citation, a position or a lift.
Kickoff
Pick ten buying questions and three competitors. You leave with the question set in writing.
Sampling
Three logged-out runs per question over three days. Thirty dated answers.
Report and walkthrough
The finding, the evidence table, three actions and a 60-minute review.
Execution check and re-run
We verify what shipped, then re-run the identical questions at day 60.
$850, one brand, one question set.
Invoiced before kickoff. Includes the 8-page PDF, the answer-level workbook, one revision and the day-60 re-run.
If the format is not a fit, the free three-question check and the synthetic sample are enough to decide before you pay.
| Buying questions | 10 |
| Dated answers | 30 |
| Competitors | 3 |
| Source audit | Included |
| Report and workbook | 8 pages + 30 rows |
| Walkthrough | 60 minutes |
| Re-run | Day 60 |
| Price | $850 one-time |
Tell us the category and the three competitors you lose to.
We reply within one business day with whether the diagnostic is a fit. If it is not, we will say so and point you at the free sample.
No newsletter. No sequence. One reply from a person.
Questions
Is this a ChatGPT rank tracker?
No. There is no stable rank across logged-out AI sessions. The diagnostic reports mention rate, position, citations and variance for a dated sample.
Which questions do you ask?
Ten buying questions chosen with you, including best-of, alternatives, how-to-choose and pricing. We do not use a generic prompt list.
Do you need access to our analytics?
No. We use the public category, your website, your three competitors and the questions you approve.
What happens after the report?
You get three prioritised actions with owners and success measures. We check execution at day 30 and re-run the identical questions at day 60.
Can you guarantee we will be cited?
No. We can show what the answers currently say and which sources they use. We cannot control a model’s answer.