AI answers your buyers with a short list. Is one of them you?
We ask the questions your buyers ask, log the answer word for word, and trace every source it cites. The free check gives you three answers. The diagnostic runs thirty, over three days, so you can see what is stable and what is noise.
One answer is an anecdote. Three answers show a range.
AI answers move between runs. A brand can be absent at 9am and second at 2pm without anyone changing a page. A single check is a screenshot; a diagnostic is a series.
We run every question three times and report the runs, not a smoothed number that hides the disagreement.
Synthetic example. The point is the spread, not the brand. The free check gives you one run per question; the diagnostic gives you three.
What the $850 diagnostic actually contains.
Ten questions your buyers ask, thirty dated answers, and the reading that turns them into a plan. The report is built to be forwarded, not logged into.
Ten buying questions
Chosen with you, in the language your buyers use, not a generic prompt list.
Thirty dated answers
Three logged-out runs per question over three days. Every answer kept, including the ones that disagree.
Competitor position
Mention and recommendation rates against three named competitors, with the questions where they appear and you do not.
Source audit
Every citation classified: directories, communities, editorial, first-party, video. What the answers read, and what they ignored.
Three actions
Prioritised by effort and evidence, each with a success measure and the page or profile that owns it.
Day-60 re-run
The same question set, re-run after the work. A before/after page that shows what moved and what did not.
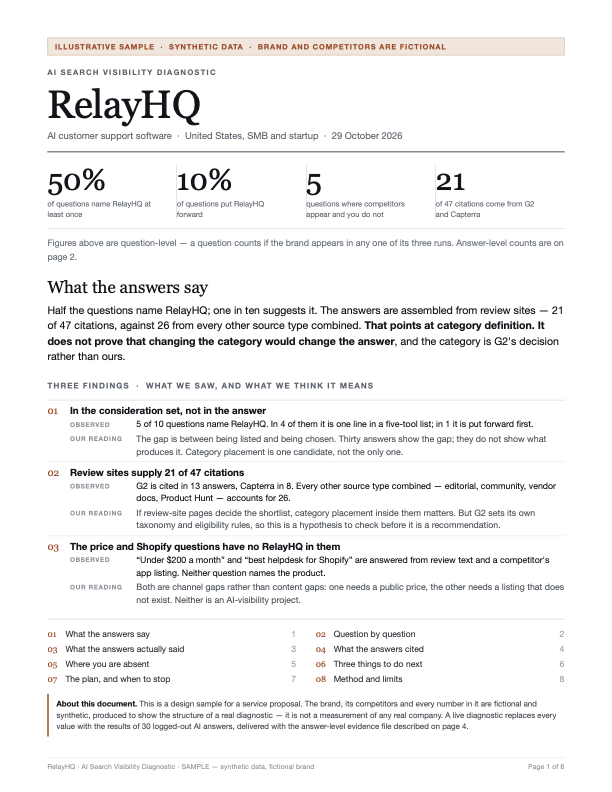
A document you can forward, not a dashboard you have to interpret.
Eight pages, dated, with the answer-level workbook behind it. The first page is the finding; page 4 is the evidence table; page 8 is the method and limits. No login, no seat, no export button to hunt for.
The sample is synthetic and says so on every page. The structure, the evidence table and the limits are the real deliverable.
Open the 8-page sampleThe method is the product.
A tracker samples a synthetic panel and gives you a number. We sample logged-out answers, keep the dates, and read them by hand. The reading is what you are buying.
Every claim in the report traces to a dated answer and the sources that answer cited. If the answer changed between runs, you see both.
That AI answers are stable. That a single “ranking” exists. That a citation proves a claim. That any of this is guaranteed.
Answers vary by session, location and model. We show the variance instead of hiding it.
Pick the questions
Thirty minutes with you. Ten questions your buyers actually ask, plus the three competitors you lose to.
Sample, logged out
Three runs per question over three days, one location, no account history. Thirty dated answers.
Read and classify
Every mention, recommendation and citation is logged. Variance stays visible; we do not average it away.
Walk through, then re-run
A 60-minute walkthrough, three actions, a day-30 execution check and a day-60 re-run.
Two ways to buy. One baseline.
Start with the diagnostic. Monitoring only makes sense after a baseline, because a trend without a starting point is just another screenshot.
The report is invoiced before kickoff. Monitoring is month-to-month, with 30 days' notice. No annual lock-in.
| Deliverable | Diagnostic | Monitoring |
|---|---|---|
| Buying questionsChosen with you | 10 | Same set |
| Dated answersLogged out, three runs each | 30 | Weekly |
| CompetitorsNamed in the report | 3 | 2 brands |
| Source auditCitations classified | Included | Monthly |
| ReportPDF + evidence workbook | 8 pages | Change log |
| WalkthroughLive review | 60 min | 30 min / month |
| Re-runSame questions | Day 60 | Weekly |
| Price | $850 one-time | $350 / month |
| Terms | Invoiced before kickoff | 30 days' notice |
Both include one revision round. New brands or question sets are quoted separately. Monitoring is only offered after a diagnostic.
Tell us the category and the three competitors you lose to.
We reply within one business day with whether the diagnostic is a fit. If it is not, we will say so and point you at the free sample.
No newsletter. No sequence. One reply from a person.
Questions worth asking before you buy.
Is this just a ChatGPT rank tracker?
No. There is no stable “rank” across logged-out AI sessions. We sample the answers, keep the dates, and report mention rate, position in the answer, cited sources and variance. The free check uses Perplexity Sonar as a fast web-grounded proxy; the paid diagnostic uses logged-out ChatGPT sessions and can add a second surface when scoped.
Why three runs per question?
One answer is an anecdote. Three dated runs show whether a brand is consistently absent, consistently present, or moving between runs. The diagnostic reports the spread rather than hiding it behind one average.
Can you guarantee we will be cited?
No. We can show what the answers currently say, which sources they cite, and the work most likely to change the inputs. We cannot control a model's answer, and we will not promise a ranking or a citation.
How long does the diagnostic take?
The report is delivered within five business days of the kickoff call. The day-30 execution check and day-60 re-run are included. Monitoring, if you continue, is weekly after that.
Is the sample report a real client?
No. The sample is labelled synthetic on every page. RelayHQ is a fictional company; the structure, evidence table and limits are real. We do not show a client logo or result until a client has approved one.